How to Build an SEO-Friendly Website Architecture
A sound site architecture makes page relationships, crawl paths, URLs, and language variants understandable to people and search engines.
Why architecture matters for search
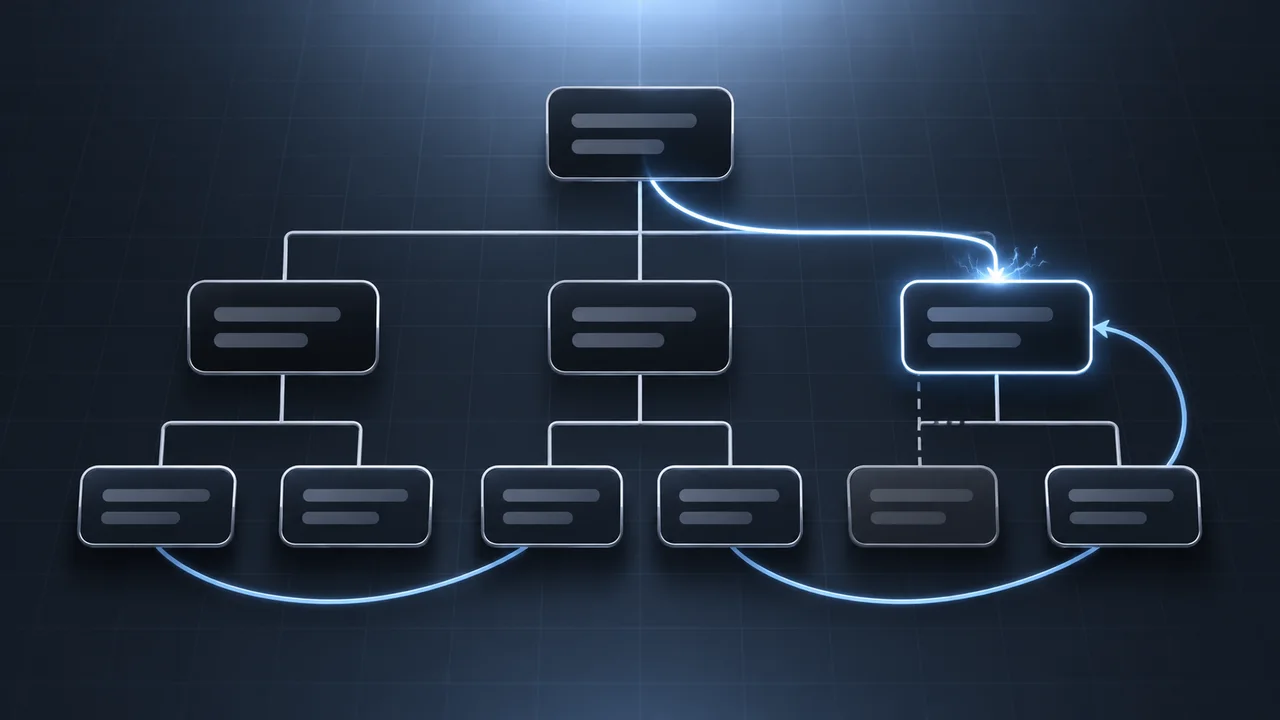
Website architecture defines how information is grouped, how pages connect, and how a visitor moves toward an answer. The same structure helps crawlers discover URLs and understand relationships between topics. Good architecture does not guarantee rankings; it reduces avoidable obstacles to discovery, interpretation, and navigation.
Start with user needs and page hierarchy
Identify the main audience tasks and topics before drawing a sitemap. Group them into understandable areas such as service pages, project pages, guides, FAQs, and trust information. Every page should have a clear purpose and receive links from relevant pages.
A common pattern connects the home page to service areas, then to individual service pages, with supporting articles nearby. Excessive depth and vague categories make important routes difficult to find. Putting every topic on one long page can blur the boundaries between different user needs.
Use clear, stable URLs
A URL should be descriptive, reasonably concise, and stable where possible. Avoid unnecessary parameters, opaque identifiers, and repeated slug changes. When a URL must change, redirect the old address to the closest relevant destination. Long redirect chains and unrelated redirects create poor experiences.
Build internal links around the next useful step
An internal link should help a reader continue. An educational article can point to a related service; a service page can link to a guide that helps evaluate the decision; a project page can show a relevant example. Anchor text should describe the destination. Do not add links simply to repeat a keyword.
Create a simple map of the home page, commercial pages, supporting articles, and portfolio examples. Give each article one primary commercial destination and a small number of related resources. When two pages compete for the same search purpose, clarify their roles: the article explains the problem, while the service page explains the commercial offer and how to proceed.
Crawlability, indexability, and low-value URLs
Not every reachable URL deserves to be indexed. Internal search results, endless filters, duplicate parameters, and thin archives can create large sets of low-value pages. Decide whether each page type should be crawlable, indexable, canonicalized, or marked noindex.
The XML sitemap should advertise canonical, indexable URLs and remain current. Internal links should resolve to valid destinations. Removed pages should return an appropriate response such as 404 or 410 based on their status; do not redirect every removed URL to the home page.
Multilingual SEO and language direction
Give each language its own URL and natural editorial content. Related language versions should reference one another with hreflang, and each version should normally have a self-referencing canonical. Translation alone does not guarantee that the content matches the needs of a different language audience.
Text direction, headings, breadcrumbs, image alternative text, and navigation should work in both RTL and LTR. Persian and English keyword targets are not necessarily direct translations; research the audience's language-specific needs separately.
Page semantics and structured data
Unique titles, useful descriptions, one clear H1, logical H2/H3 hierarchy, and visible page content help people understand a page. Structured data must match what visitors can actually see and must not invent authors, dates, or ratings. Performance, accessibility, and mobile usability are part of technical page quality as well.
Architecture review checklist
- Every page has a defined purpose and audience.
- Important pages are reachable through meaningful links.
- URLs are descriptive and stable.
- Canonical, hreflang, and page language agree.
- Filter and duplicate-parameter URLs are controlled.
- The sitemap lists appropriate canonical URLs.
- Broken links and redirect chains are resolved.
- Service pages and articles do not target the same intent without a clear distinction.
Reconcile the information architecture with existing pages
Inventory current URLs before adding another category or guide. A service page may already cover the commercial topic, while a new article should answer a distinct informational question rather than create a near-duplicate. Record each URL's title, purpose, audience, publication state, canonical, and incoming links. This simple inventory helps identify pages with overlapping roles or no clear purpose.
Taxonomy should use language visitors understand. Vague internal labels, deep nesting, and tags used by only one article make navigation harder. Keep a small set of meaningful groups, and promote an archive for indexing only when it contains a substantial, distinct collection.
Change structure without losing useful paths
When a page is merged, removed, or renamed, its destination should be the closest useful answer to the previous intent. Redirecting every removed URL to the home page is not a sound substitute. After a change, review internal links, canonical, hreflang, and the sitemap, then monitor 404 responses and redirect chains.
For a multilingual site, maintain Persian and English as independent content experiences. If one language does not have a genuine equivalent article, do not invent an hreflang relationship to an unrelated page. Language alternates should represent real equivalents.
Conclusion
SEO architecture begins with information design and user journeys, not a handful of technical tags added at the end. Clear structure, contextual links, and deliberate indexability rules help crawlers discover important pages and help visitors make informed decisions.
Review Uzap's SEO service. A useful starting point is an inventory of current URLs, important commercial pages, and the paths visitors use to reach them.